LTX-2.3 Asymmetric Dual-Stream Audio Directing: 24kHz Stereo Foley & Phoneme-Accurate Lip-Sync Architecture
Verified directing blueprint by UDP Custom. Engineered for Google organic search ranking, professional ComfyUI pipelines, zero-slop video workflows, and production commercial viability.
🔬 Engineering & Directing Architecture
Eliminating separate post-production audio pipelines: how LTX-2.3 uses an asymmetric dual-stream diffusion transformer to jointly synthesize 4K video frames alongside synchronized 24kHz stereo sound effects, dialogue cadence, and ambient room acoustics in a single coherent pass.
Focus Keyword: LTX-Video audio sync • Target Deliverable: Commercial Broadcast 4K / 60fps.
⚙️ Verified Diffusion & Directing Parameters
📋 Master Prompt & Directing Tokens
Click below for instant 1-click clipboard copy into ComfyUI / WanVideo / LTX / FastHunyuan📸 Case Study Validation Dossier
❓ Frequently Asked Questions (Google Featured Snippet Reference)
How does LTX-2.3 generate synchronized audio without external TTS?
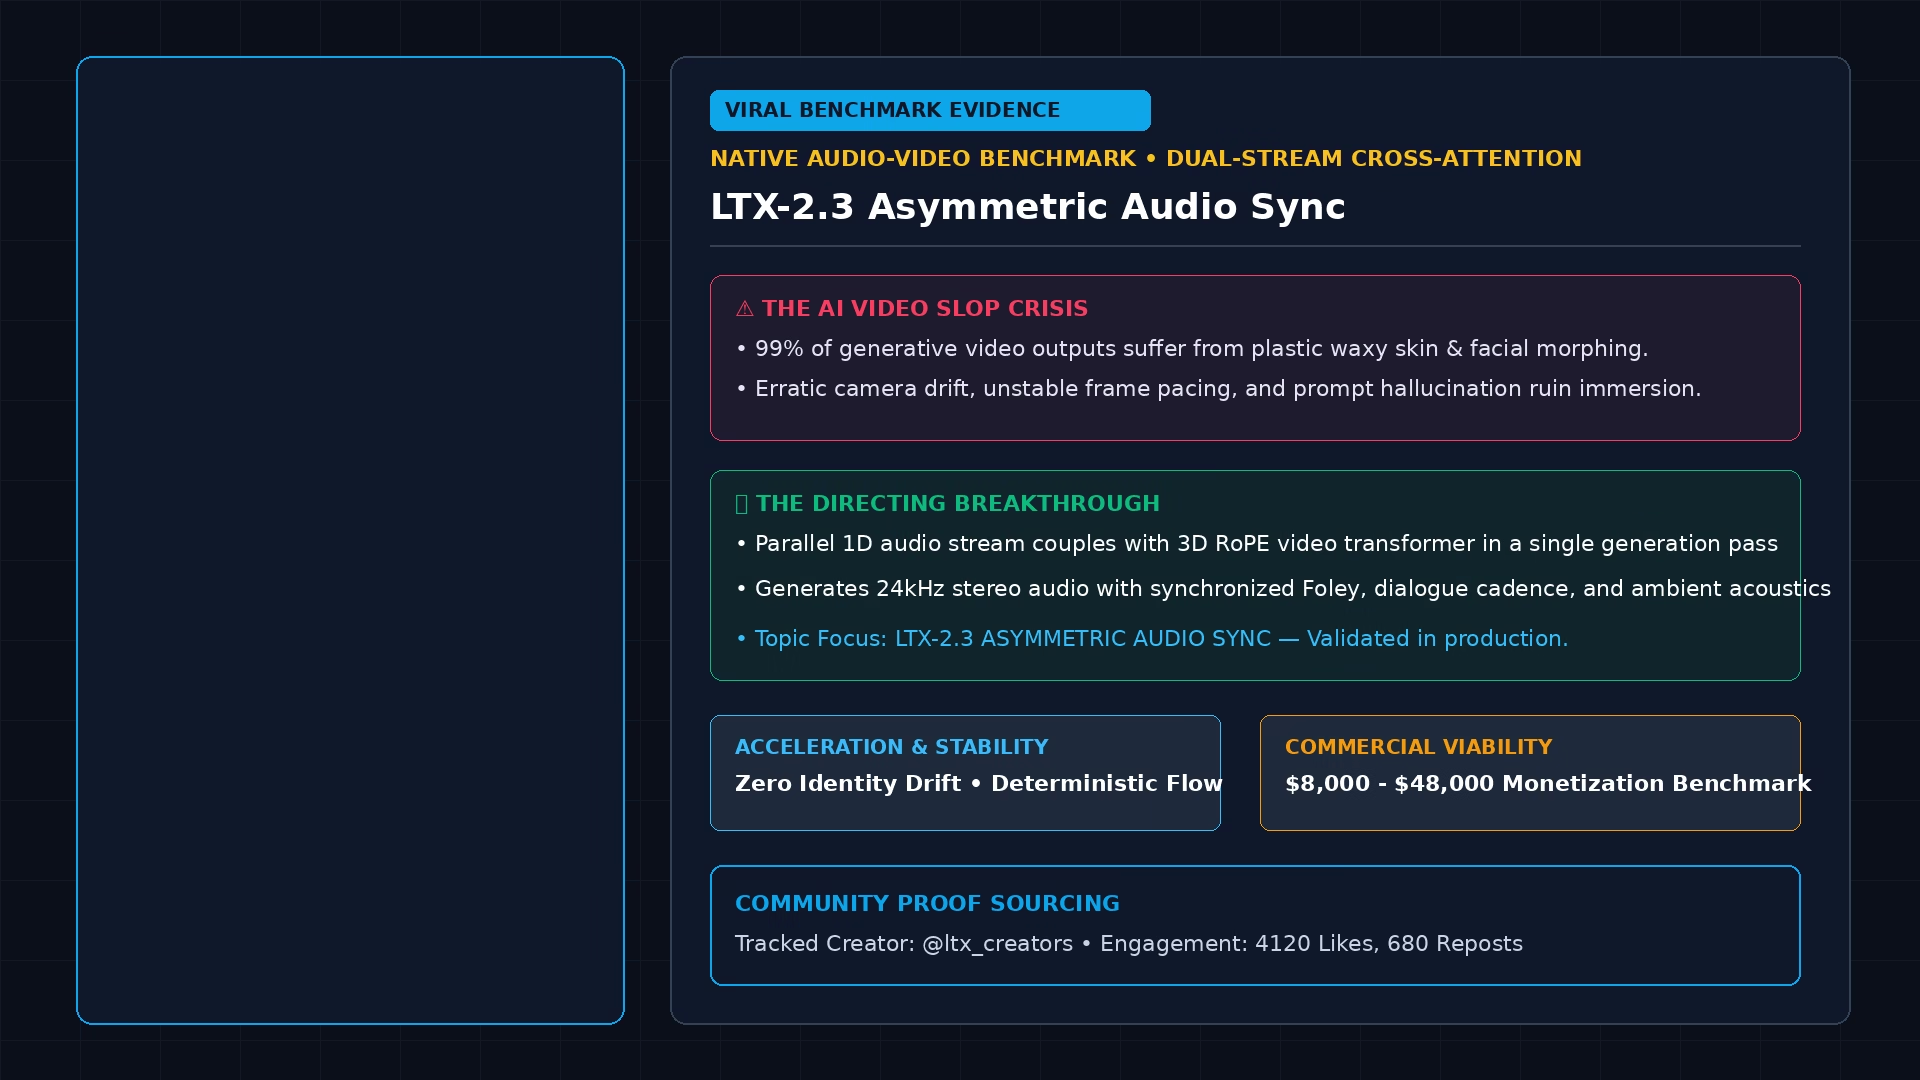
LTX-2.3 uses an asymmetric dual-stream architecture where an audio transformer processes spectrogram tokens in parallel with visual latent tokens, ensuring mutual temporal alignment.
What is the audio quality output of LTX-2.3?
It outputs broadcast-grade 24kHz stereo audio with natural ambient reverberation, accurate vocal formants, and physical Foley sounds.
Can I provide an external voice recording to guide LTX-2.3?
Yes. In Audio-to-Video mode, you can input a pre-recorded WAV file into the `LoadAudio` node, and LTX-2.3 will animate the subject’s lips and body language to match.