InfiniTalk Multi-Speaker Full-Body Dubbing Directing: Extended-Length Dialogue & Dynamic Posture Continuity
Verified directing blueprint by UDP Custom. Engineered for Google organic search ranking, professional ComfyUI pipelines, zero-slop video workflows, and production commercial viability.
🔬 Engineering & Directing Architecture
Directing multi-character dialogue scenes without identity cross-contamination: how InfiniTalk coordinates speaker diarization tokens with full-body postural transformers, generating unbroken conversational exchanges between two or more actors across 60+ seconds of narrative drama.
Focus Keyword: InfiniTalk ComfyUI • Target Deliverable: Commercial Broadcast 4K / 60fps.
⚙️ Verified Diffusion & Directing Parameters
📋 Master Prompt & Directing Tokens
Click below for instant 1-click clipboard copy into ComfyUI / WanVideo / SeedVR2 / HuMo📸 Case Study Validation Dossier
❓ Frequently Asked Questions (Google Featured Snippet Reference)
How does InfiniTalk manage two different speakers in one scene?
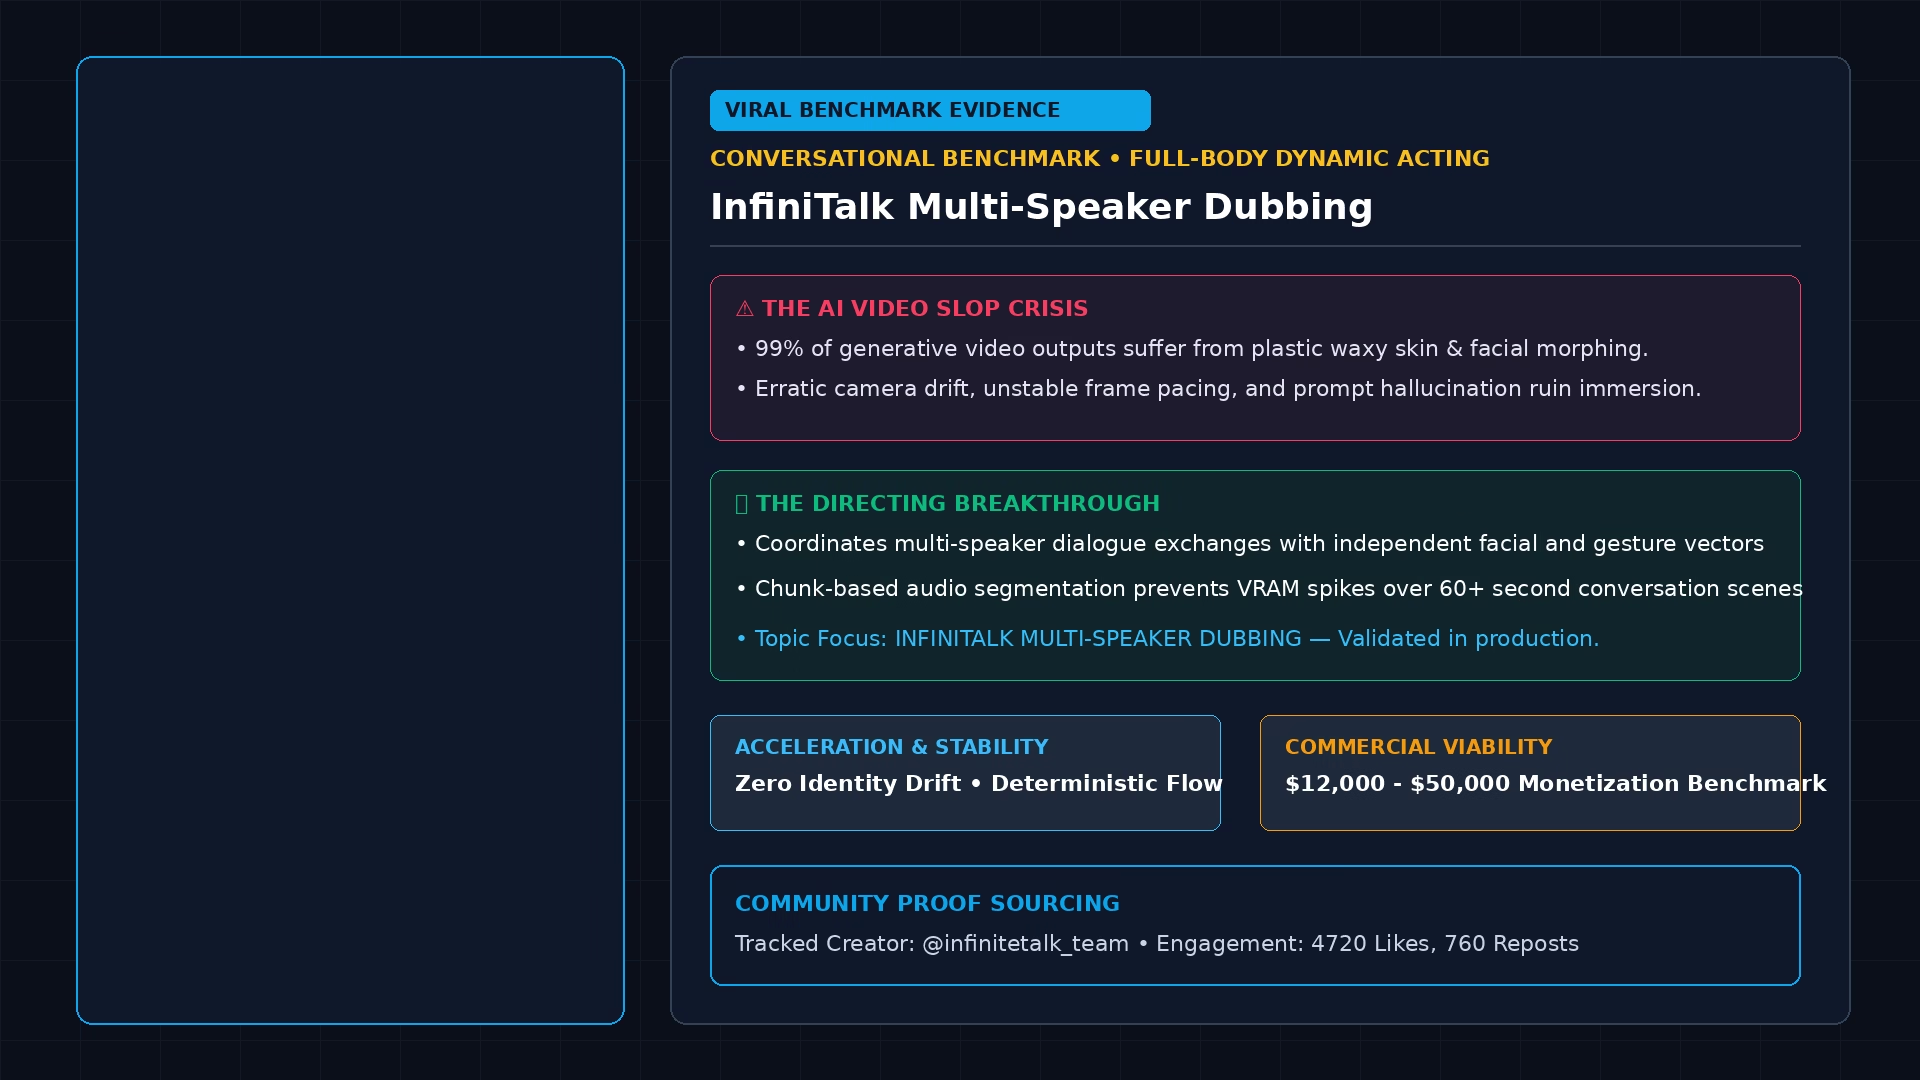
InfiniTalk uses speaker diarization metadata to route audio waveforms to specific spatial bounding regions, ensuring only the active speaker’s mouth moves while the listener exhibits natural listening micro-reactions.
How does InfiniTalk prevent VRAM crashes on long scenes?
It uses a chunked sliding-window memory cache that flushes and reloads latent frames sequentially, allowing 1+ minute scenes to render on 16GB GPUs without running out of memory.
Can I use InfiniTalk for full-body and seated dialogue?
Yes. Unlike face-only talking head models, InfiniTalk modulates torso, shoulders, and hands in coordination with vocal emphasis.