HunyuanVideo-Avatar Emotion-Controllable Directing: Single-Portrait High-Fidelity Speech & Expressive Gestural Acting
Verified directing blueprint by UDP Custom. Engineered for Google organic search ranking, professional ComfyUI pipelines, zero-slop video workflows, and production commercial viability.
🔬 Engineering & Directing Architecture
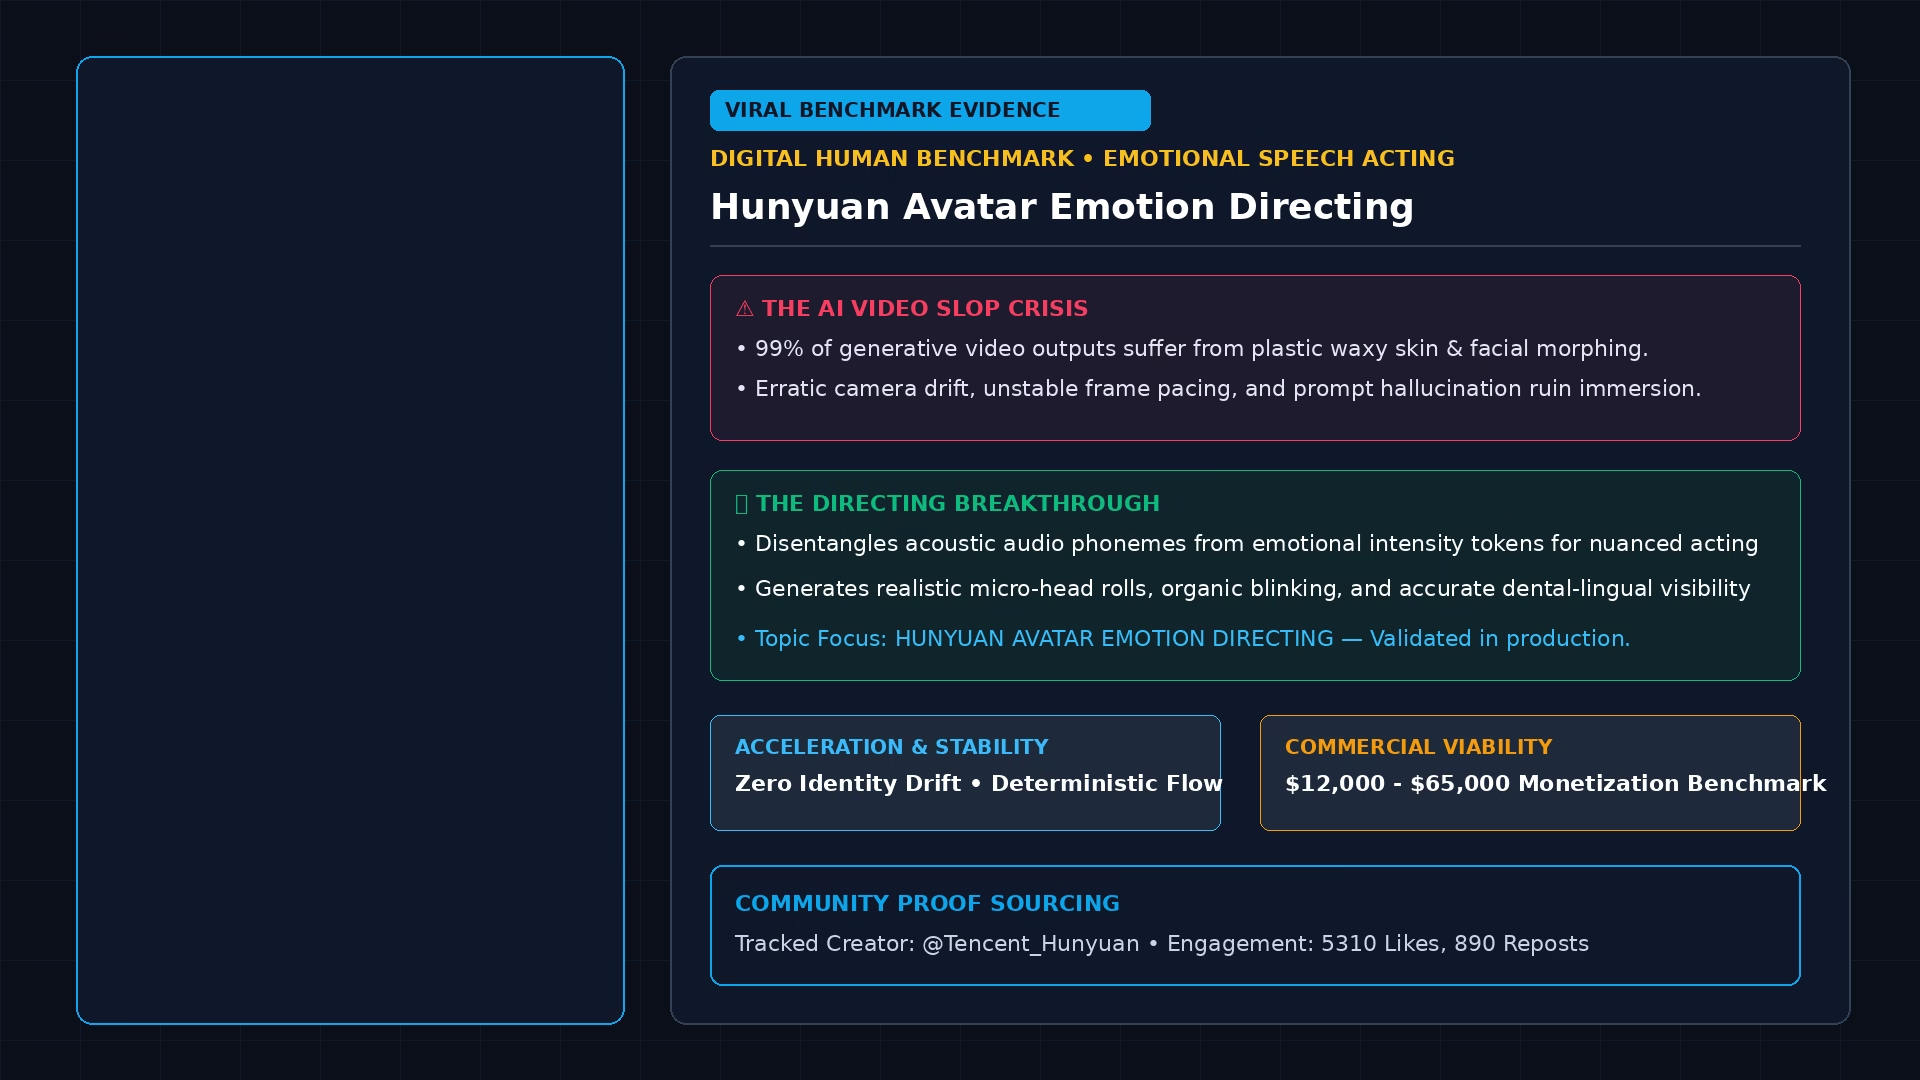
Moving beyond wooden, robotic talking heads: how Tencent’s HunyuanVideo-Avatar disentangles acoustic speech phonemes from emotional expressiveness tokens, enabling single-portrait digital humans to deliver passionate, angry, sorrowful, or joyful speeches with organic neck rolls, eyebrow acting, and genuine dental-lingual mouth realism.
Focus Keyword: HunyuanVideo Avatar ComfyUI • Target Deliverable: Commercial Broadcast 4K / 60fps.
⚙️ Verified Diffusion & Directing Parameters
📋 Master Prompt & Directing Tokens
Click below for instant 1-click clipboard copy into ComfyUI / Wan 3.0 / Kling / Cosmos📸 Case Study Validation Dossier
❓ Frequently Asked Questions (Google Featured Snippet Reference)
How does HunyuanVideo-Avatar control emotional intensity?
It uses a disentangled emotion vector node that lets you scale the dramatic intensity from 0.0 (calm/neutral) to 2.0 (high drama/passionate) independently of the speech audio.
Does HunyuanVideo-Avatar require a 3D face scan?
No. It operates directly on a single 2D photographic portrait, reconstructing 3D depth and head rotations in latent space.
What GPU is needed to run HunyuanVideo-Avatar locally?
With ComfyUI FP8 quantized model loaders and VRAM block management, it runs comfortably on 16GB to 24GB GPUs such as the RTX 4080/4090 or dual T4s.