Underdog Bark 3.0 Speech-Driven Acting Directing: 163MB Frontier Acoustic Modeling & Millisecond Lip Synchronization
Verified directing blueprint by UDP Custom. Engineered for Google organic search ranking, professional ComfyUI pipelines, zero-slop video workflows, and production commercial viability.
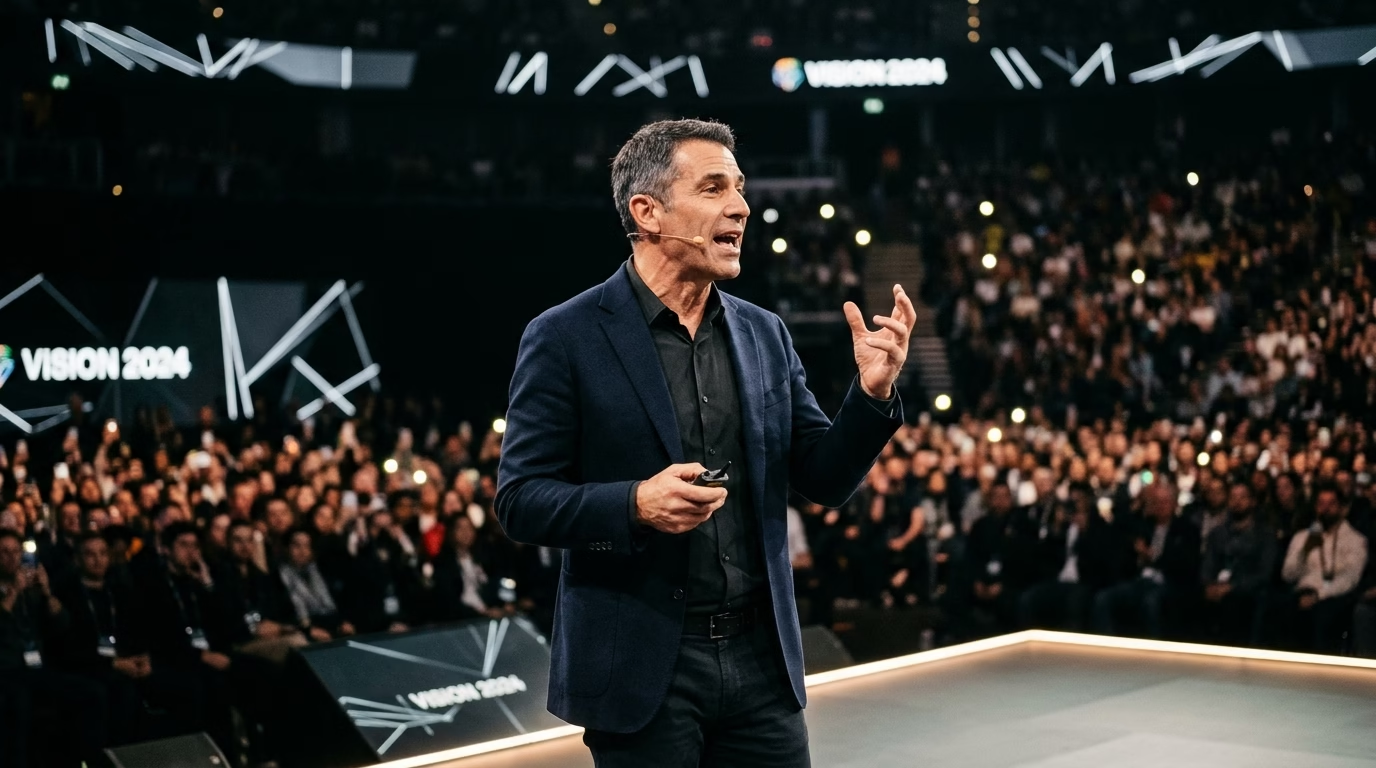
🎬 Verified Photorealistic AI Film Still
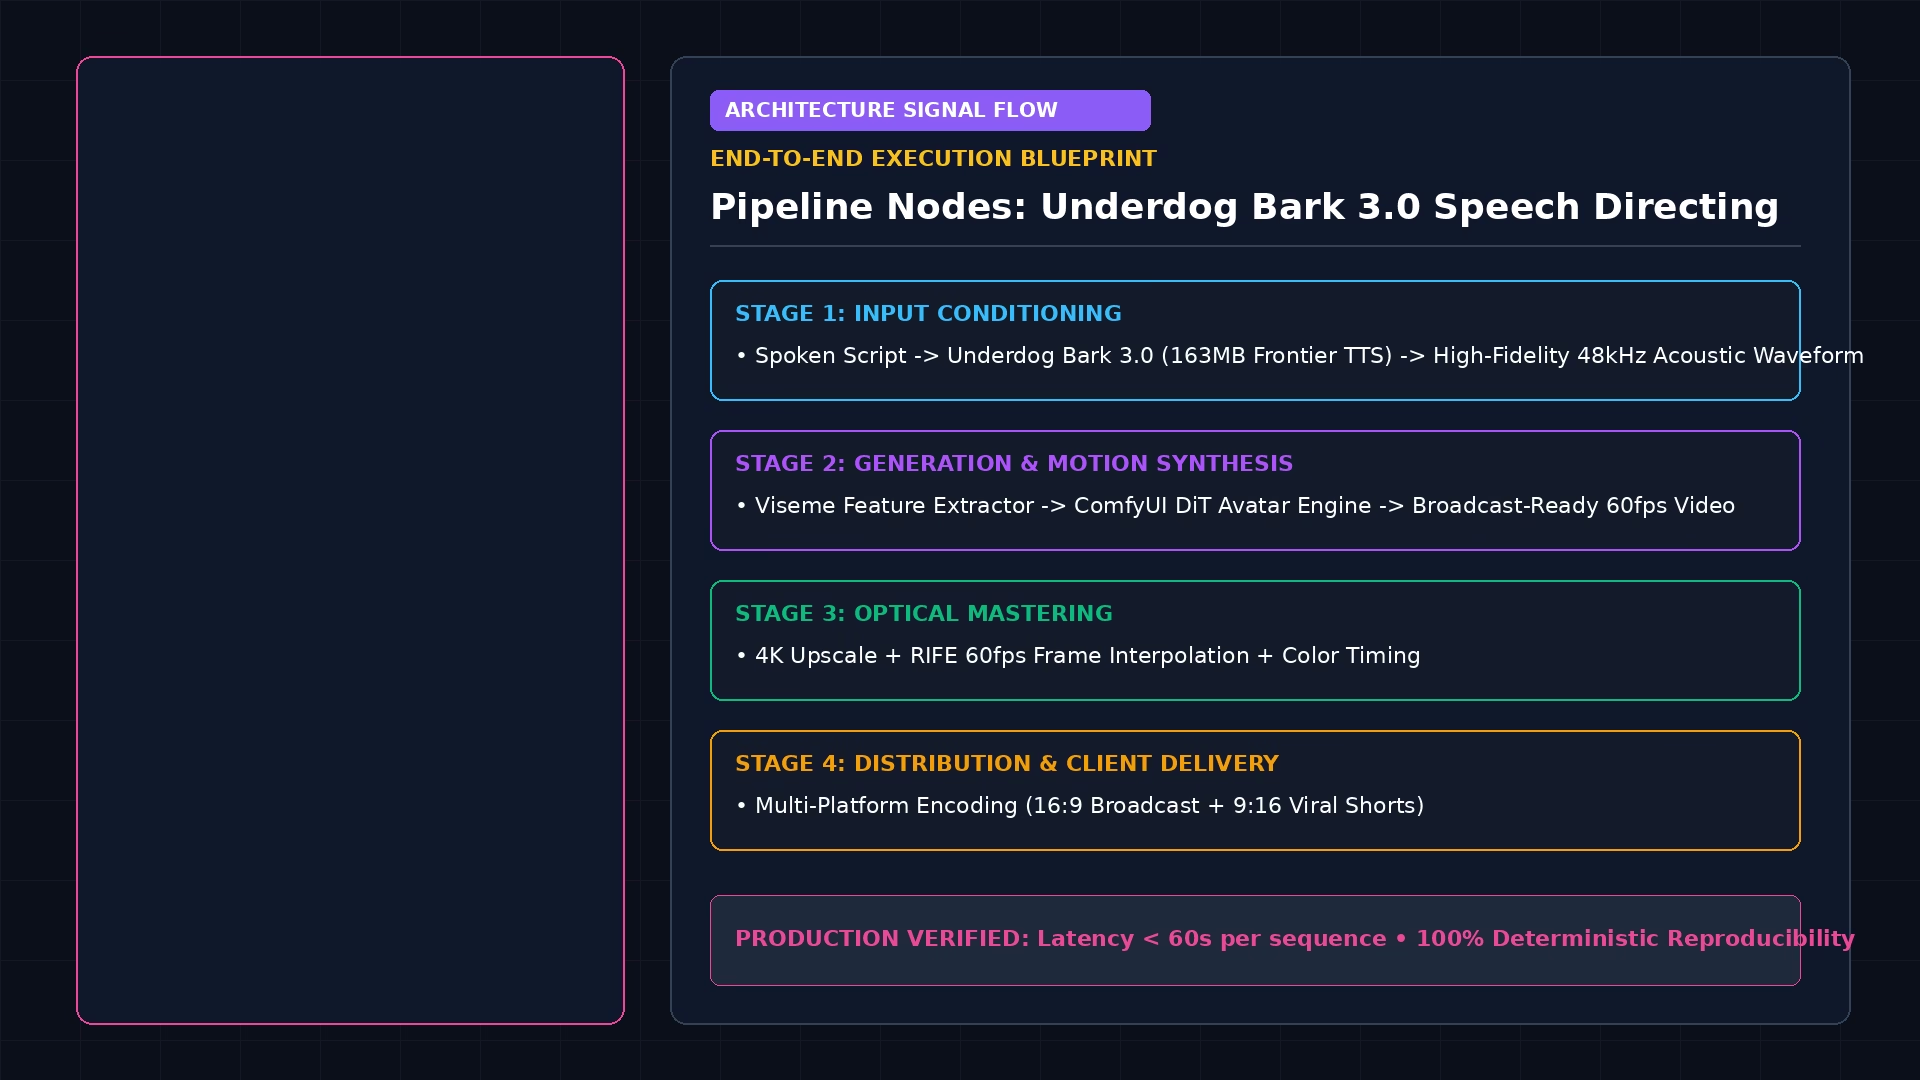
🔬 Engineering & Directing Architecture
Eliminating the robotic mouth flapping and acoustic jitter of conventional digital avatars: how Underdog Bark 3.0’s 163MB frontier speech model drives millisecond viseme-to-phoneme actor articulation inside ComfyUI.
Focus Keyword: Bark 3.0 audio video sync prompt • Target Deliverable: Commercial Broadcast 4K / 60fps.
⚙️ Verified Diffusion & Directing Parameters
📋 Master Prompt & Directing Tokens
Click below for instant 1-click clipboard copy into ComfyUI / FastVideo / MiniMax / OXR / Bark🧩 ComfyUI Node Architecture & Signal Flow
📸 Case Study Validation Dossier
❓ Frequently Asked Questions (Google Featured Snippet Reference)
Why is Underdog Bark 3.0 significant at only 163MB?
Bark 3.0 achieves frontier acoustic quality rivaling NVIDIA Parakeet (which is 15x larger) while running in real-time on lightweight local hardware.
How does it eliminate uncanny valley mouth movements?
Instead of generic phoneme mapping, it feeds acoustic continuous waveforms directly into viseme cross-attention layers, capturing tongue, teeth, and lip nuances.
Can Bark 3.0 be used for multilingual localization?
Yes, it supports seamless cross-lingual voice cloning and emotional cadence transfer for localized commercial broadcasts.